Your learning journey
New to Kolla-Ansible Day-2 operations? Follow these five stages in order. Each stage groups a few pages of this study,
from the easiest to the most detailed. You do not need to read everything at once: come back whenever you like.
Lumo, your guide
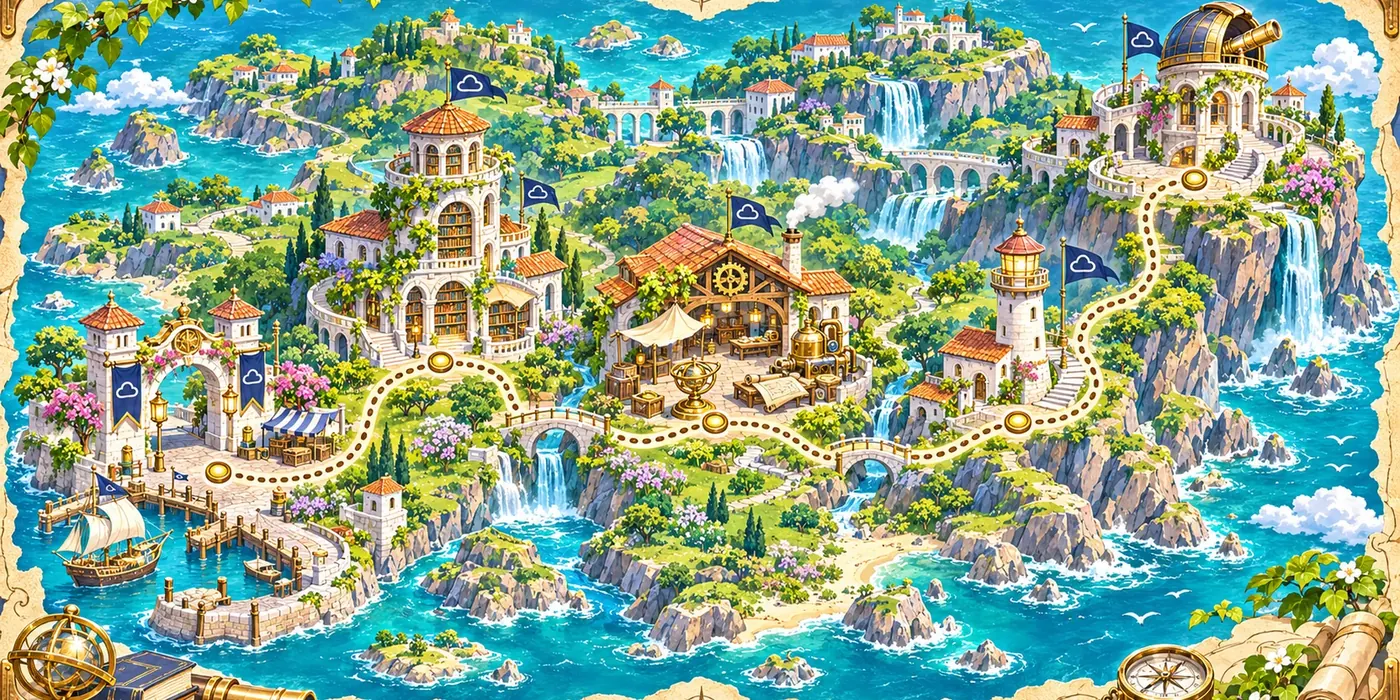
Here is the map of the island: five stages, from the harbour to the observatory. Go at your own pace. When the
source code does not establish something, the page says NOT AVAILABLE : we never guess.
1 Discover2 Understand3 Practise4 Judge the risks5 Master
How to use the journey
Open a page of the stage you are at, read it, then tick Mark this page as read at the bottom.
The bar under the title of each page tells you where you are, and the buttons take you to the previous or next
step. Many pages end with To remember , the few ideas to keep, then What would you do? , a situation from a real platform with three ways to
react, and Check yourself , a short quiz. Each stage ends with a final challenge
below: read its pages and pass the challenge to earn the seal of the stage. Your progress is kept in this browser
only: nothing is sent anywhere.
Why this order
The first stages explain how the pages are written and what happens when a command runs. With that in mind,
the procedures of the later stages make sense instead of being recipes to copy.
Lumo: practise safely
The study is a reading of the source code: nothing in it was run against a host. Try what you learn on a
test platform, never first on production.
Three levels
Each page of this study shows its level under its title, so that you know what to expect:
Discover the conventions, the essentials and the concepts: start here.Practise the operations, the risks and troubleshooting: once the concepts are clear.Master the components in depth and the detailed evidence: to go further.
The five stages
Stage 1 of 5 · completed
Discover
Get your bearings: how the pages are written, the essentials, and the words used everywhere.
Conventions and evidence labels read Ten things to know before a production run read Glossary read Find it fast read
Final challenge of the stage: 5 questions
Lumo: 5 questions on the whole stage. Get at least 4
right on the first try, with every page of the stage marked as read, and the seal of
Discover is yours. You can try again as often as you like.
1. You change one global setting on the deployment host, for example a RabbitMQ or memcached membership or a password. Why can this small central change restart containers across the whole fleet?
Because Kolla-Ansible restarts every container after any change, whatever it is Because global settings land in per-host files, including compute-side configs Because the change is copied to the hosts only by a full pull of the images
Show the answer
Answer: Because global settings land in per-host files, including compute-side configs. Global settings land in per-host files: enable_*, RabbitMQ/memcached membership and passwords end up in compute-side configs, so small central changes cause fleet-wide restarts.
Read the page .
2. You rebuilt an image and pushed it under the same tag, then ran deploy. The containers still run the old image. Why?
deploy never pulls an image that is already present; rebuilt images under the same tag need pulldeploy pulled the image but only reconfigure recreates containersdeploy skips every image whose tag is unchanged until genconfig has run
Show the answer
Answer: deploy never pulls an image that is already present; rebuilt images under the same tag need pull. deploy never pulls an image that is already present. Rebuilt images under the same tag need pull.
Read the page .
3. A service uses config_strategy COPY_ONCE instead of the default COPY_ALWAYS. What happens to a config change when its container is only restarted?
It is applied, because kolla_set_configs copies the config on every container start It is applied by a reload, without stopping the container It is not re-applied: under COPY_ONCE the config is copied only on the first start, so only a recreate re-applies it
Show the answer
Answer: It is not re-applied: under COPY_ONCE the config is copied only on the first start, so only a recreate re-applies it. COPY_ALWAYS, the default, copies the config and applies permissions on every container start. COPY_ONCE does it only on the first start of a container, so only a recreate re-applies config CODE .
Read the page .
4. An operation page shows the impact class restarts-on-drift under its title. What does that tell you?
Every command of the page restarts all containers of the service At least one command of the page can restart containers, only if drift is detected The command renders config and restarts no Docker container
Show the answer
Answer: At least one command of the page can restart containers, only if drift is detected. restarts-on-drift means the command can restart containers, only if drift is detected. A class says that at least one command of the page has that impact, not that all do; "renders config and restarts no Docker container" is writes-config.
Read the page .
5. During an incident, what can the portal tell you, and what mostly not?
What Kolla will do given the inputs (tasks and restarts); what that does to VMs and APIs depends on the environment and is mostly NOT AVAILABLE What happened to your VMs during the last run, because the study observed real runs Nothing: the study only covers initial deployment, not incidents
Show the answer
Answer: What Kolla will do given the inputs (tasks and restarts); what that does to VMs and APIs depends on the environment and is mostly NOT AVAILABLE . During an incident, the portal can tell what Kolla will do given the inputs: tasks and restarts. What that does to VMs and APIs depends on the environment and is mostly NOT AVAILABLE in these sources.
Read the page .
Stage 2 of 5 · completed
Understand
See how Kolla-Ansible is built and what happens, step by step, when a command runs.
Repository architecture read Deployment execution flow read Kolla images: start path and one-shot containers read Compute scaling and performance read
Final challenge of the stage: 5 questions
Lumo: 5 questions on the whole stage. Get at least 4
right on the first try, with every page of the stage marked as read, and the seal of
Understand is yours. You can try again as often as you like.
1. globals.yml sets a variable, and you set a different value for one host in the inventory host_vars. Which value does that host get, and why?
The globals.yml value: it is passed as extra-vars, the highest precedence in Ansible The host_vars value: per-host settings always win over global ones The group_vars/all.yml default: it is read last
Show the answer
Answer: The globals.yml value: it is passed as extra-vars, the highest precedence in Ansible. globals.yml is passed with -e @file, which is extra-vars, so a value in globals.yml cannot be overridden per host or per group in the inventory CODE . Per-host variation must come from variables that are not set in globals.yml.
Read the page .
2. With kolla_serial set, the nova-cell play runs batch by batch over the computes. When are the neutron agents on compute001 restarted?
Right after compute001's own batch finishes the nova-cell play Only after all computes have finished the nova-cell and openvswitch plays Never: batching skips the handlers
Show the answer
Answer: Only after all computes have finished the nova-cell and openvswitch plays. A batch runs the complete play, handler restarts included, before the next batch starts, but each play is still traversed batch by batch for the whole fleet before the next play starts.
Read the page .
3. All of memcached's settings are in the command of its config.json ("config_files": []). Why does kolla_set_configs --check never make a memcached setting change restart the container?
Because memcached has no systemd unit to compare Because --check compares command only for one-shot containers Because --check iterates only config_files, so this manifest always returns 0
Show the answer
Answer: Because --check iterates only config_files, so this manifest always returns 0. --check never compares config.json's command and permissions: it iterates only config_files, so a manifest with "config_files": [], like memcached's, always returns 0.
Read the page .
4. Why does a no-change -t nova reconfigure still cost a lot of work on a large fleet?
Because Kolla has no "only if changed" short-circuit at play level: every compute runs the full per-host chain Because every task restarts the nova containers to be safe Because the image of every compute is pulled again
Show the answer
Answer: Because Kolla has no "only if changed" short-circuit at play level: every compute runs the full per-host chain. Every run that includes the compute group executes the full per-host chain on every compute, even with no change: config re-rendering and comparison, container config checks, common role, sysctl and modules, OVS post-config, discovery. Nothing restarts, and yet at 500 computes the run still costs about 23,000 remote invocations.
Read the page .
5. Why is restarting a container enough to apply a changed or added config file?
Because the service watches its files and reloads them Because with COPY_ALWAYS, kolla_set_configs copies the files listed in config.json at every container start Because the restart handler pulls a new image
Show the answer
Answer: Because with COPY_ALWAYS, kolla_set_configs copies the files listed in config.json at every container start. The config.json manifest tells kolla_set_configs which files to copy from /var/lib/kolla/config_files; with config_strategy: COPY_ALWAYS the copy happens at every container start. That is why Kolla-Ansible never applies config by reloading a service.
Read the page .
Stage 3 of 5 · completed
Practise
Prepare a command before running it: check, predict, then apply one service or one batch at a time.
Pre-execution checklist read Predict and inspect a run read Reconfigure a single service read Write config first, apply in controlled batches read Command quick lookup by tag read
Final challenge of the stage: 5 questions
Lumo: 5 questions on the whole stage. Get at least 4
right on the first try, with every page of the stage marked as read, and the seal of
Practise is yours. You can try again as often as you like.
1. You change only the command of memcached in its config.json (for example its -m option), run genconfig, then kolla_set_configs --check as root in the memcached container. What happens?
It exits 0: command is not compared and memcached has an empty config_files, so the change is not seen as drift It exits 1: any change to config.json is drift and the next run restarts memcached It exits 2: the check fails the task on that host
Show the answer
Answer: It exits 0: command is not compared and memcached has an empty config_files, so the change is not seen as drift. 0 = every file listed in config_files matches its live copy; command and permissions are not compared, so memcached ("config_files": []) always returns 0 CODE . Such drift takes effect only at the next restart for another reason.
Read the page .
2. You run ANSIBLE_SERIAL=10 kolla-ansible -i multinode -t nova reconfigure. How often does compute discovery run?
Once for the whole run, because it is run_once On the first compute of each nova-cell batch, so once per batch that contains computes Never: discovery is skipped when serial is set
Show the answer
Answer: On the first compute of each nova-cell batch, so once per batch that contains computes. A run_once task runs once per batch of its own play; compute discovery runs on the first compute of each nova-cell batch, so it repeats once per batch that contains computes CODE .
Read the page .
3. In Ussuri, does kolla-ansible -t keystone reconfigure also check and possibly restart the common containers (fluentd, cron, toolbox) on the keystone hosts?
No: common runs only under -t common No: a service tag touches only its own containers and its frontend file Yes: common is a meta dependency, so it inherits the tag and runs on every host of the service play, with restarts if drift
Show the answer
Answer: Yes: common is a meta dependency, so it inherits the tag and runs on every host of the service play, with restarts if drift. The keystone play runs common on keystone hosts first: the meta dependency inherits the tag, and common does fluentd/cron/toolbox config plus a container check, restarting if drift.
Read the page .
4. In Ussuri, with the default settings, does -t neutron reconfigure run a one-shot neutron DB sync container?
Yes, on every reconfigure No: none by default, because the neutron db sync is deploy-only while neutron_enable_rolling_upgrade is yes Yes, once per batch when ANSIBLE_SERIAL is set
Show the answer
Answer: No: none by default, because the neutron db sync is deploy-only while neutron_enable_rolling_upgrade is yes. The quick lookup table gives "none by default" for -t neutron reconfigure; likewise the untagged reconfigure runs the db sync of every enabled service except neutron.
Read the page .
5. Step 1 of the checklist runs kolla-ansible genconfig with the same tags and --limit before the real run. Can it restart anything in Ussuri?
Yes: with enable_hyperv, the unguarded nova-hyperv handlers can restart Windows services, so keep Hyper-V hosts out of the --limit No, never: genconfig only prints the config it would render Yes: it restarts every drifted container, like reconfigure
Show the answer
Answer: Yes: with enable_hyperv, the unguarded nova-hyperv handlers can restart Windows services, so keep Hyper-V hosts out of the --limit. genconfig writes config but does not restart any Docker container, because every container restart handler has when: kolla_action != "config". Exception: the deprecated nova-hyperv role's handlers are unguarded, so with enable_hyperv genconfig can restart the Windows nova-compute, neutron-hyperv-agent and FreeRDP-WebConnect services.
Read the page .
Stage 4 of 5 · completed
Judge the risks
Learn what a tag really touches, why small changes can grow, and which risks and bugs are known.
What a tag really executes read Why a small change creates a large workload read Risk register read Known bugs and limitations read
Final challenge of the stage: 5 questions
Lumo: 5 questions on the whole stage. Get at least 4
right on the first try, with every page of the stage marked as read, and the seal of
Judge the risks is yours. You can try again as often as you like.
1. You add one extra controller to the inventory. Why is this small change a large workload?
It changes the transport URL in every messaging service everywhere Only the new controller gets containers; the rest of the cloud is untouched Only HAProxy restarts, to add the new backend
Show the answer
Answer: It changes the transport URL in every messaging service everywhere. One extra controller changes the transport URL in every messaging service everywhere, so the change reaches far beyond the new host.
Read the page .
2. A config change concerns only one container of a role. Why can every container of that role on that host restart?
Because Kolla restarts every container of a host after any config change Because the loop result is changed if any item changed, and then the handler of every executed item is notified Because the handlers of a role are tagged with the role name
Show the answer
Answer: Because the loop result is changed if any item changed, and then the handler of every executed item is notified. Loop notify: if any item changed, the templated handler name of every executed item is notified, so a change that concerns one container restarts every container of that role on that host CODE . Skipped items do not notify.
Read the page .
3. You set a new enable_* flag in globals.yml and run reconfigure -t nova. Can common's cron container restart on the nova hosts?
No: -t nova touches only Nova containers No: only -t common reaches the common config Yes: -t nova also runs common on every nova host, and the logrotate config lists services by their enable_* flags
Show the answer
Answer: Yes: -t nova also runs common on every nova host, and the logrotate config lists services by their enable_* flags. -t nova also runs common on every nova host and compute CODE , and common's cron logrotate config lists services by their enable_* flags and notifies Restart cron container. Meanwhile -t common is a no-op.
Read the page .
4. A service image is rebuilt and pushed under the same tag. You run reconfigure without pull. What happens?
The containers of that service are recreated with the new image Nothing changes: only absent images are pulled The run fails because the image digests differ
Show the answer
Answer: Nothing changes: only absent images are pulled. This is R13: nothing changes (only absent images are pulled). After pull: recreate, plus loop-notify restarts. Precautions: use immutable tags; always pull deliberately.
Read the page .
5. You change only the command in a container's config.json, then run genconfig + deploy-containers. Is the change applied?
No: kolla_set_configs --check compares only config_files entries, so the change is not applied until the container restarts for another reason Yes: kolla_set_configs --check detects it and the container restarts Yes, but only on the first host of the group
Show the answer
Answer: No: kolla_set_configs --check compares only config_files entries, so the change is not applied until the container restarts for another reason. kolla_set_configs --check compares only config_files entries: changes confined to config.json (command, permissions) are never detected, so neither genconfig + deploy-containers nor a later run applies them until the container restarts for another reason CODE .
Read the page .
Stage 5 of 5 · completed
Master
Go deeper: how the components depend on each other, the detailed findings, and the limits of what is known.
Component dependencies read Nova deep dive read Technical findings read Method and limits of the study read What is not known read
Final challenge of the stage: 5 questions
Lumo: 5 questions on the whole stage. Get at least 4
right on the first try, with every page of the stage marked as read, and the seal of
Master is yours. You can try again as often as you like.
1. On a fresh cloud where Keystone was never deployed, you run kolla-ansible deploy -t nova. What happens?
Kolla deploys Keystone first, because the nova role declares a dependency on it The run fails at Keystone registration: nothing enforces a dependency when you use tags Nova deploys fine and registers itself in Keystone later, once Keystone is deployed
Show the answer
Answer: The run fails at Keystone registration: nothing enforces a dependency when you use tags. Nothing enforces a dependency when you use tags: --tags filters plays, and -t nova on a fresh cloud fails at Keystone registration if Keystone was never deployed CODE . Kolla-Ansible never declares inter-service dependencies explicitly: role meta lists only common.
Read the page .
2. You set enable_barbican: yes. The flag changes nova.conf and also common's fluentd and cron files. Does a nova run restart cron, fluentd and kolla_toolbox on the nova hosts?
Yes: common is a meta dependency of nova and nova-cell, so its container check restarts them on every nova host No: a nova run never touches the common containers, which restart only when a separate common play runs Only kolla_toolbox restarts, because it is a deploy-time dependency of nova
Show the answer
Answer: Yes: common is a meta dependency of nova and nova-cell, so its container check restarts them on every nova host. enable_barbican also changes the common role's td-agent.conf and cron logrotate.conf. common is a meta dependency of nova and nova-cell, so its container check also restarts cron, fluentd and kolla_toolbox on every nova host (loop-notify) CODE .
Read the page .
3. You run kolla-ansible deploy with --limit set to one new compute host. Why does work still run on control01?
Because --limit is ignored by every play that includes the compute group It does not: --limit confines every action to the hosts you name Because delegate_to: groups[x][0] runs work on hosts outside the limit: the Neutron DB create/grant, the bootstrap_neutron container and cell discovery
Show the answer
Answer: Because delegate_to: groups[x][0] runs work on hosts outside the limit: the Neutron DB create/grant, the bootstrap_neutron container and cell discovery. --limit does not confine actions: delegate_to: groups[x][0] runs work on hosts outside the limit CODE . With deploy --limit set to a compute host, control01 runs the Neutron DB create/grant and the bootstrap_neutron container, plus cell discovery, so "only the new compute" still executes DB-sync containers on a controller.
Read the page .
4. With enable_neutron_agent_ha: yes, the L3 agent wrapper runs neutron-netns-cleanup --force --agent-type l3 before the agent starts. What is established about the routers on that node when neutron_l3_agent restarts?
They keep north-south and floating-IP traffic, because the namespaces persist across the restart Nothing: whether they lose north-south and floating-IP connectivity until rebuilt, and whether HA routers fail over, is not established They always lose all traffic until an operator rebuilds them by hand
Show the answer
Answer: Nothing: whether they lose north-south and floating-IP connectivity until rebuilt, and whether HA routers fail over, is not established. The cleanup at start is CODE , but whether with the cleanup the routers on that node lose north-south and floating-IP connectivity until rebuilt, and whether HA routers fail over, is NOT AVAILABLE . What neutron-netns-cleanup itself does is neutron code.
Read the page .
5. The study shows from the code exactly which containers a run restarts on a compute. What does it say about the impact of those restarts on running VMs and the data plane, and why?
It is not available: the study rests only on reading source code, and no container or VM behaviour is used as evidence It is measured: lab runs on real computes show how long VMs lose traffic There is no impact: a restart that the code shows is always safe for running VMs
Show the answer
Answer: It is not available: the study rests only on reading source code, and no container or VM behaviour is used as evidence. No container or VM behaviour is used as evidence: every statement about data-plane or VM impact is NOT AVAILABLE . The study rests only on reading source code, and there are no timings.
Read the page .
beginner
learning

 Discover
not started
 Understand
not started
 Practise
not started
 Judge the risks
not started
 Master
not started
 Journey
not started