← Production Guide · Compute operations
PG-09 · Emptying a host for patching?
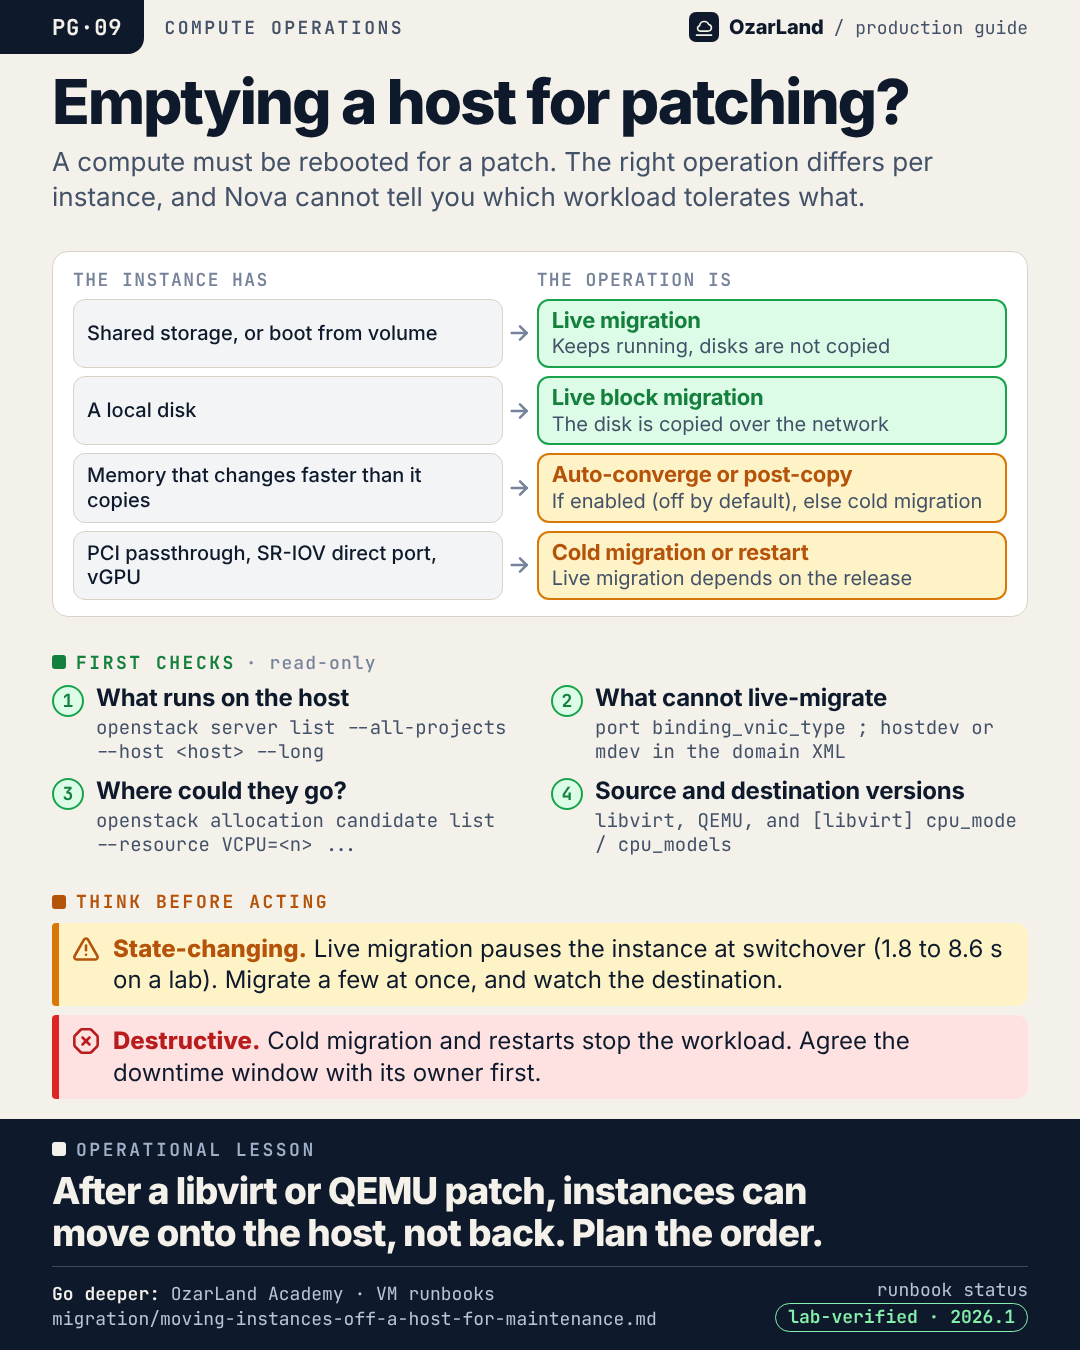
Operational lesson. After a libvirt or QEMU patch, instances can move onto the host, not back. Plan the order.
The memo as text
Situation. A compute must be rebooted for a patch. The right operation differs per instance, and Nova cannot tell you which workload tolerates what.
First checks (read-only):
- What runs on the host:
openstack server list --all-projects --host <host> --long - What cannot live-migrate:
port binding_vnic_type ; hostdev or mdev in the domain XML - Where could they go?:
openstack allocation candidate list --resource VCPU=<n> ... - Source and destination versions:
libvirt, QEMU, and [libvirt] cpu_mode / cpu_models
Think before acting:
- ⚠️ State-changing. Live migration pauses the instance at switchover (1.8 to 8.6 s on a lab). Migrate a few at once, and watch the destination.
- 🛑 Destructive. Cold migration and restarts stop the workload. Agree the downtime window with its owner first.
Go deeper
This memo is a memory aid. The procedure, with every command, its risk warning and its limits, is in the runbook:
- Moving instances off a compute host for planned maintenance ·
lab-verifiedon 2026.1 · highest risk in the page: destructive - Live migration runs for a long time, then is aborted. The instance writes memory faster than it can be copied ·
drafton 2026.1 · highest risk in the page: state-changing
Where this holds. Derived from a patching campaign on a platform of up to several hundred hosts (release not recorded). Disable, live block migration and re-enable were lab-verified on 2026.1; cold migration and shared-storage live migration were not. Migration from a newer libvirt or QEMU to an older one is not supported. Constraints for PCI, SR-IOV, vGPU and CPU models depend on the release: check the Nova documentation of yours. A running instance keeps the old QEMU binary until it is migrated or restarted.
LinkedIn kit
- Image:
dist/pg-09-emptying-a-host-for-maintenance.png(1080 × 1350) - Post title: Emptying a compute host: one operation does not fit every instance
A compute needs a reboot for a kernel or QEMU patch. "Just live-migrate everything" is rarely the whole answer.

The operation depends on the instance:
→ shared storage or boot from volume: live migration
→ local disk: live block migration, the disk travels over the network
→ memory changing faster than it copies: auto-converge or post-copy if enabled (off by default), else cold migration
→ PCI passthrough, SR-IOV direct ports, vGPU: cold migration or restart, depending on your release

And one trap of every patching campaign: migration from a newer libvirt/QEMU to an older one is not supported. Once a host is patched, instances can move onto it, but not back. The order of patching decides where instances can go.

Nova cannot tell you which workload tolerates a pause or a restart. The owning teams can.

Runbook: https://github.com/OzarLand/ozarland-academy/blob/main/docs/runbooks/migration/moving-instances-off-a-host-for-maintenance.md
More memos: https://github.com/OzarLand/ozarland-academy/tree/main/docs/production

#OpenStack #Nova #LiveMigration #Patching #CloudOperations #OzarLand
Source: emptying-a-host-for-maintenance.yml. Found an error, or does your platform behave differently? Open an issue or see CONTRIBUTING.