← Production Guide · Control plane
PG-17 · APIs fail on database errors?
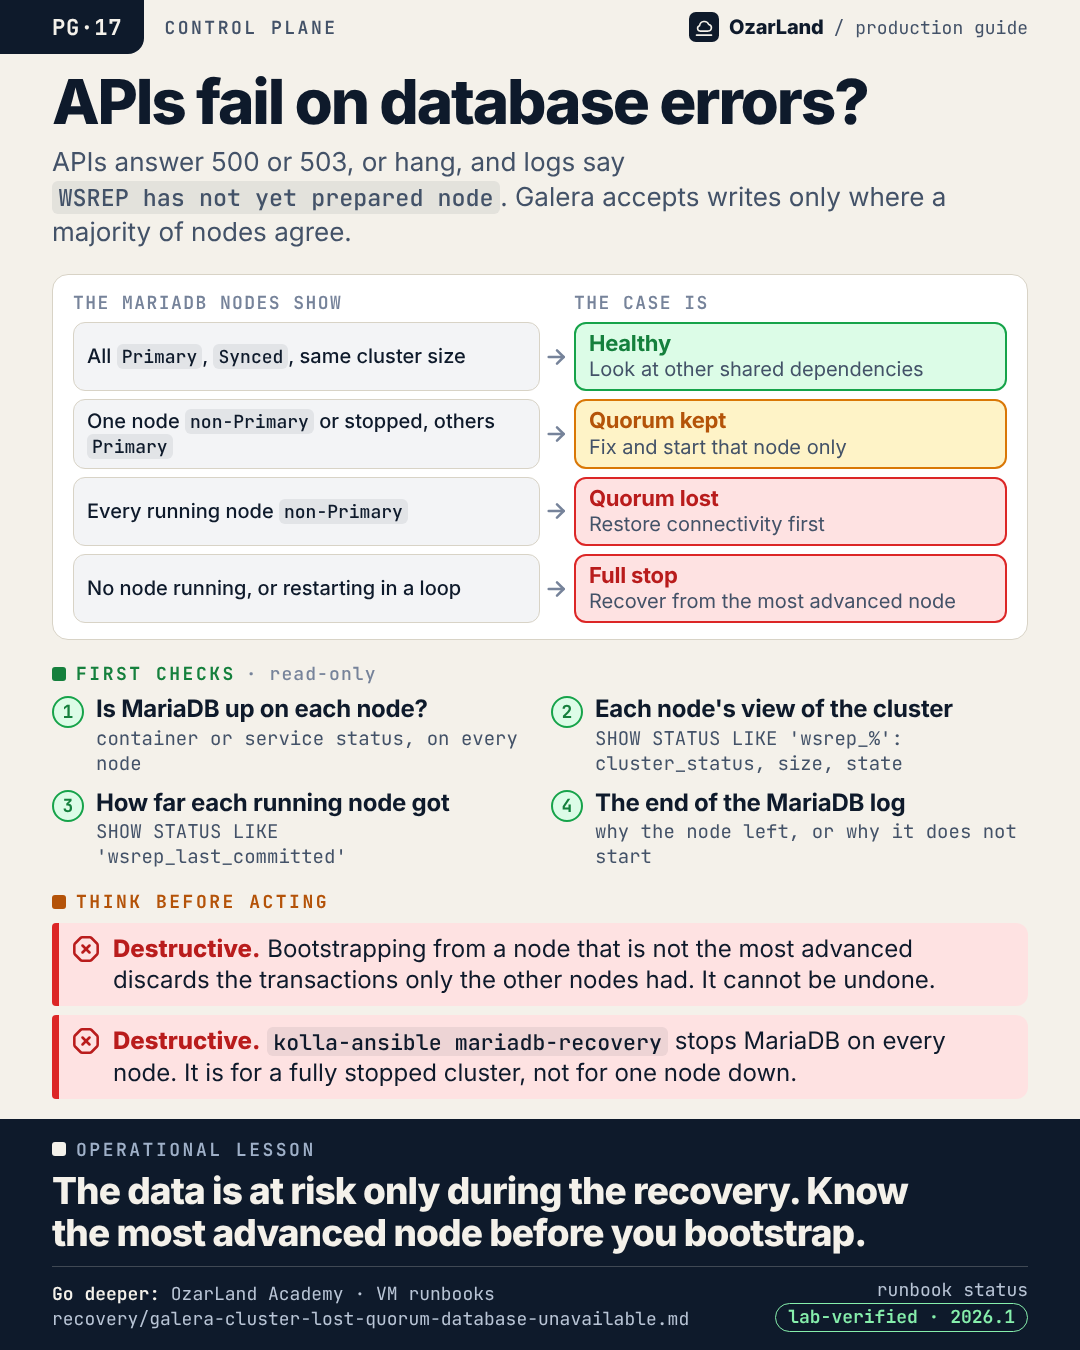
Operational lesson. The data is at risk only during the recovery. Know the most advanced node before you bootstrap.
The memo as text
Situation. APIs answer 500 or 503, or hang, and logs say WSREP has not yet prepared node. Galera accepts writes only where a majority of nodes agree.
First checks (read-only):
- Is MariaDB up on each node?:
container or service status, on every node - Each node's view of the cluster:
SHOW STATUS LIKE 'wsrep_%': cluster_status, size, state - How far each running node got:
SHOW STATUS LIKE 'wsrep_last_committed' - The end of the MariaDB log:
why the node left, or why it does not start
Think before acting:
- 🛑 Destructive. Bootstrapping from a node that is not the most advanced discards the transactions only the other nodes had. It cannot be undone.
- 🛑 Destructive.
kolla-ansible mariadb-recoverystops MariaDB on every node. It is for a fully stopped cluster, not for one node down.
Go deeper
This memo is a memory aid. The procedure, with every command, its risk warning and its limits, is in the runbook:
- Every API fails on database errors. The Galera cluster lost quorum, or stopped on every node ·
lab-verifiedon 2026.1 · highest risk in the page: destructive
Where this holds. Written from Kolla-Ansible 2026.1 and the Galera crash recovery and quorum reset guides; lab-verified on a disposable Kolla-Ansible lab with ProxySQL in front of MariaDB. With ProxySQL the services see its errors ("Max connect timeout reached") instead of the WSREP message. Running instances keep running. Single-node MariaDB and restoring from a backup are not covered. With every node stopped, wsrep_last_committed cannot be queried: the position comes from --wsrep-recover. A quorum reset run on both sides of a split creates two clusters.
LinkedIn kit
- Image:
dist/pg-17-galera-lost-quorum.png(1080 × 1350) - Post title: Galera lost quorum: the data is at risk during the recovery, not before
Most OpenStack APIs fail or hang. The logs show database errors: "WSREP has not yet prepared node for application use", or a ProxySQL connect timeout.

Galera accepts writes only in a Primary component, a majority of the last known nodes. Lose the majority and the remaining nodes refuse queries. That is a safety mechanism, not the failure.

Running instances keep running. And the data is not at risk yet. It becomes at risk during the recovery, if the cluster is bootstrapped from a node that is not the most advanced: the transactions only the other nodes had are discarded, for good.

So before any recovery command, on every node:
→ is MariaDB running?
→ wsrep_cluster_status: Primary or non-Primary?
→ wsrep_last_committed: how far did this node get?

One node down, quorum lost and full stop are three different cases with three different answers.

Runbook: https://github.com/OzarLand/ozarland-academy/blob/main/docs/runbooks/recovery/galera-cluster-lost-quorum-database-unavailable.md
More memos: https://github.com/OzarLand/ozarland-academy/tree/main/docs/production

#OpenStack #MariaDB #Galera #ControlPlane #DatabaseReliability #OzarLand
Source: galera-lost-quorum.yml. Found an error, or does your platform behave differently? Open an issue or see CONTRIBUTING.